

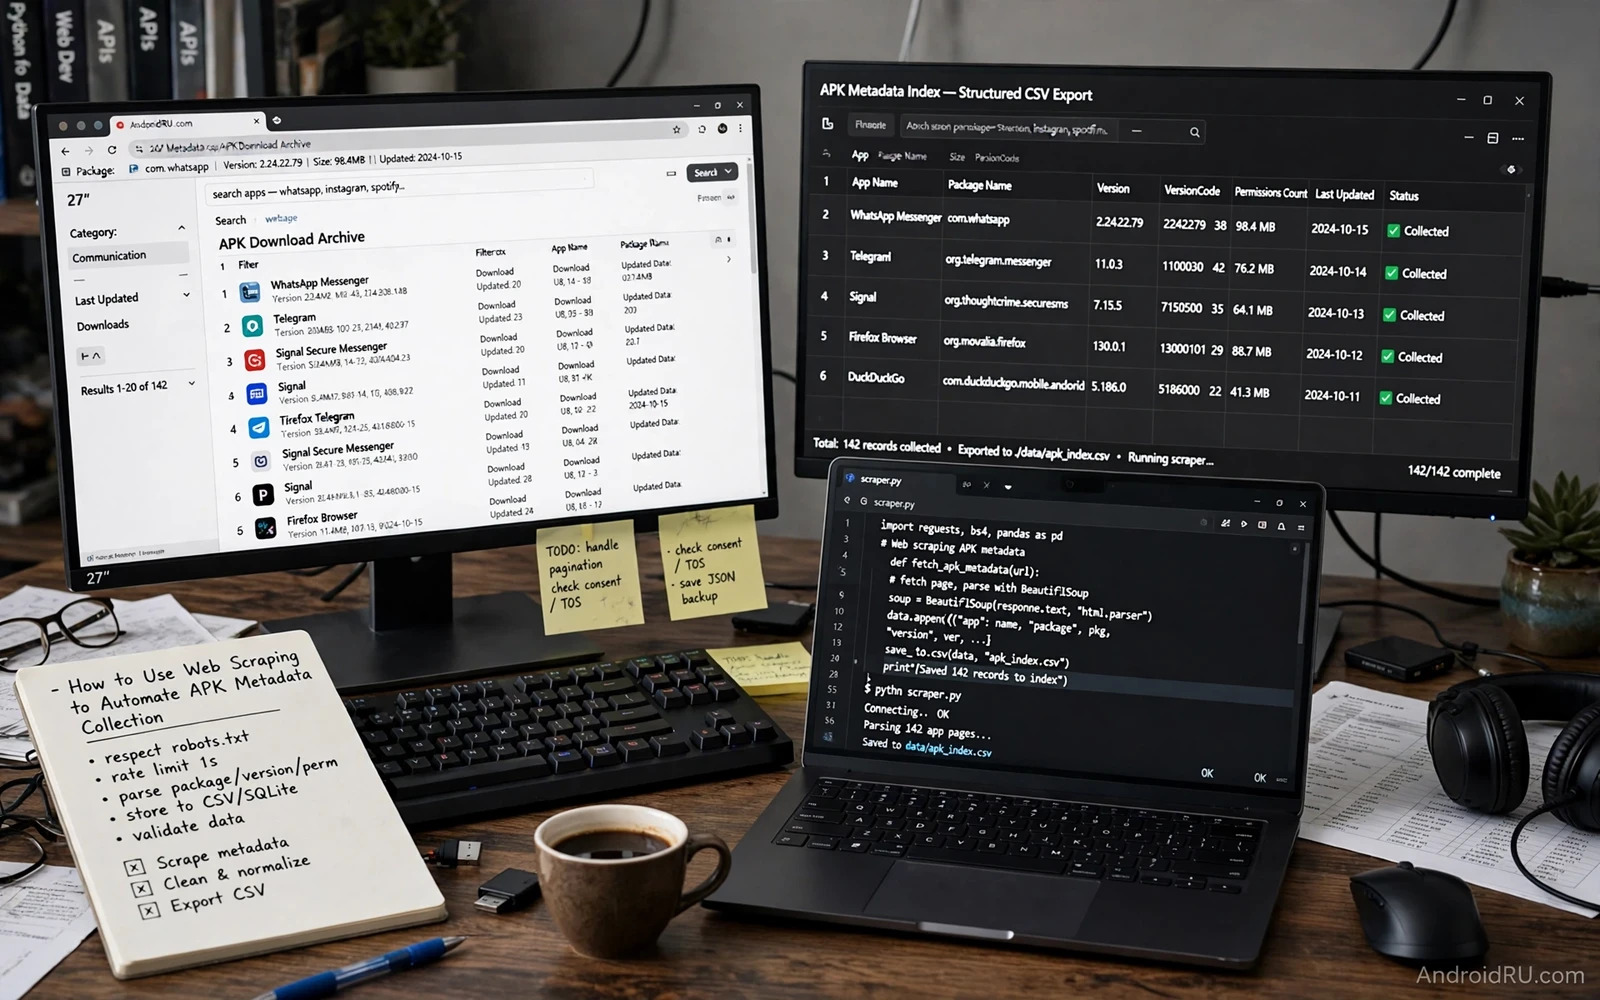
Why APK Metadata Needs Automation
An APK index is only useful when its metadata stays fresh and accurate. App titles and descriptions and version names and file sizes and update notes change often. Manual copying cannot keep up with a large catalogue and it introduces typing errors and stale entries. Automation collects the same fields in the same way every time and it makes errors easier to spot because the pattern of collection stays consistent across many apps.
Metadata also drives search and filtering and comparison on a distribution site. Users search by app name and by category and by developer name and by feature keywords. A missing field breaks a filter and a wrong version breaks trust in the whole listing. A scraper that collects a fixed set of fields and validates each field before storage protects the index from silent decay. Validation is not an optional extra when the index is the product that users rely on.
Automation does not remove human judgement. It removes repetitive copying so humans can focus on policy checks and quality review and edge cases. A scraper can flag a sudden change in a listing for review instead of publishing it blindly. That division of labour keeps the index both fast and trustworthy. The goal is a pipeline that is boring in its daily operation and clear when it needs attention.
Designing a Polite and Lawful Scraper
A scraper must respect the rules of the site it reads. Terms of use and robots rules and rate limits exist to protect the source site and its users. A polite scraper waits between requests and it identifies itself honestly and it stops when a site signals that scraping is not allowed. Aggressive scraping can overload a server and it can get an IP blocked and it can create legal risk for the project. Politeness is therefore a technical requirement and not merely good manners.
Only public metadata should be collected and no private user data should be scraped or stored. Fields such as app name and developer name and public description and public version info are the normal scope for an index. Login walls and private accounts and personal data are outside that scope. When a field is unclear the safer choice is to skip it and to document why it was skipped. A clear scope statement helps reviewers and it helps future maintainers to stay inside the same bounds.
Caching and change detection reduce load and improve accuracy at the same time. A scraper that stores a hash of each page can skip unchanged listings and focus on pages that actually changed. That approach lowers request volume and it shortens each run and it creates a clear history of when a listing changed. A history of changes also helps to debug a bad entry because the previous value and the new value are both visible.
Choosing Fields and Normalising Values
A fixed schema prevents a slow drift toward messy data. Core fields include app name and package name and developer name and category and version name and update note and description and icon reference. Each field needs a type and a length limit and a rule for missing values. A field that is sometimes a number and sometimes text will break search and sorting later. Normalisation at collection time is cheaper than cleanup after months of messy storage.
Text fields need cleaning that preserves meaning while removing junk. Extra whitespace and broken markup and duplicate lines can enter scraped text easily. Cleaning should be gentle and documented so the stored text still matches the public listing in meaning. Over aggressive cleaning can remove useful detail from a description. The cleaning rules should be tested on real listings and not only on tidy examples.
Version handling deserves special care because version names and version codes behave differently. A version name is a human readable label and a version code is an ordering value used by the system. An index that confuses the two will sort updates wrongly and will mislead users about which release is newest. Storing both values separately and checking that a new version code is greater than the stored one catches many common errors early.
From Pages to a Clean Store
A scraping pipeline has distinct stages and each stage should be testable on its own. Fetching retrieves a page and records its status and timing. Parsing extracts fields with selectors that are checked against real page structure. Validation checks types and lengths and required fields. Storage writes only validated records and keeps a log of rejected records. A failure in one stage should not corrupt records that already passed earlier stages.
Selectors break when a source site changes its layout. A scraper that depends on one fragile selector will fail silently or collect wrong data. Using several signals for a field and checking that the extracted value looks plausible reduces that risk. Alerts for a sudden drop in successful parses help the team to notice a layout change quickly. A scraper without alerts can publish stale data for days before anyone notices.
Deduplication keeps the index honest when the same app appears under several spellings or several category pages. Package name is the strongest identity key for an Android app because it stays stable while display names change. Records should be keyed by package name and display name changes should be treated as updates rather than as new apps. That rule also prevents duplicate listings that confuse users and split reviews and download counts.
Scheduling and Failure Handling
Scheduling should match how often listings actually change rather than running as fast as possible. Popular apps may need frequent checks while quiet apps can be checked less often. A schedule based on change history uses fewer requests and still catches important updates quickly. Each run should have a time limit and a clear stop rule so a hung fetch cannot block the whole pipeline for hours.
Failures should be classified rather than treated as one generic error. A network timeout is different from a blocked request and both are different from a parse failure. Retries suit transient network errors but they do not fix a blocked request or a broken selector. A retry policy that respects the source site and backs off after repeated failures protects both the scraper and the source. A failure log that records the class of error makes the next fix much faster.
Teams that maintain an APK catalogue often combine scraping with a manual index workflow and they can learn from indexing APKs for a custom distribution website to see how collected metadata becomes a browsable catalogue. That view helps a scraper author to choose fields that real catalogue pages actually need. It also shows why a missing category or a missing developer name hurts the catalogue more than a missing minor detail.
Verifying Files Alongside Metadata
Metadata alone does not prove that a file is safe or genuine. An index that also records file size and signature info and hash values gives users a stronger basis for trust. Scraped metadata should never be presented as proof of file safety when the file itself has not been checked. The metadata pipeline and the file verification pipeline should be separate stages with separate logs so a failure in one does not hide a failure in the other.
Safe handling also means clear labelling when a field is scraped and when a field is verified from the file itself. Users should be able to tell which claims come from a public listing and which claims come from a direct file check. That honesty protects users and it protects the index when a listing contains an error. A small label in the data model can carry this distinction without complicating the public page.
A practical starting point for file work is the extraction workflow described in extracting APK files from installed Android apps which shows how a real file is obtained before it is checked. Metadata scraping and file extraction answer different questions and both are needed for a trustworthy index. The scraper answers what the listing claims and the file check answers what the file actually contains.
Keeping the Pipeline Maintainable
A scraper that only one person understands will break when that person is away. Configuration should live outside code so selectors and schedules and field lists can be updated without a code release. Each change to a selector should be reviewed with a sample of real pages before it reaches production. A small test set of saved pages gives the team a stable way to check parsing after each change.
Monitoring should track success rate and parse rate and storage rate and run duration for every run. A slow decline in success rate often signals a layout change or a new block before it becomes a total failure. Dashboards that show these numbers in one place help a small team to act early. A pipeline that is monitored is a pipeline that can be trusted to run while the team sleeps.
Size work on APKs often depends on accurate metadata too and readers can follow optimizing Android APK size with ProGuard and R8 to see how build settings change the file that metadata describes. That link between build and metadata explains why version and size fields must be rechecked after each release. It also shows why a scraper should treat size as a measured value rather than as a guess.
A mature metadata pipeline is quiet and predictable. It fetches politely and parses carefully and validates strictly and stores cleanly and alerts early. It respects source rules and it keeps private data out of scope. It treats package name as identity and version code as order. When those habits are in place the index can grow without losing accuracy and the team can spend its time on quality review rather than on manual copying.
Handling Large Catalogues
A large catalogue needs pagination and checkpointing so a run can resume after a failure without starting from the beginning. Checkpoints record which packages were checked and when they were checked and what changed. A run that resumes from its checkpoint wastes fewer requests and it finishes faster after an interruption. Checkpoint design is a small investment that pays off on every large run.
Data quality checks should run after storage as well as during collection. A post storage check can find duplicate package entries and missing required fields and implausible version ordering. Those checks catch bugs that slipped through collection validation. A catalogue that checks itself after every run stays trustworthy even as the scraper and the source site both change over time.
scraper pipeline stages
fetch page with polite delay and honest identity
parse fields with checked selectors
validate types and lengths and required fields
store by package name with change history
log rejected records and alert on parse drop

